Microsoft Foundry
Microsoft Foundry is Microsoft’s platform for building and running AI applications, from ready-made models to your own agents. With Foundry Local, those models also run on your own hardware. You get current AI, even when your data can’t go to a public service.
Why Microsoft Foundry
AI tooling changes by the month, and most of it assumes your data can go to the cloud. Without a common platform, every team starts its own experiment with its own models and its own access, and nobody has the overview. Foundry gives every team the same platform to build on, under one set of rules.
Where the data is too sensitive for the cloud, Foundry Local brings the model to the data. It runs on GPUs in your own datacenter, so you use current AI models under your own control.


How you put it to work
We deploy Foundry Local on Azure Kubernetes Service on your Azure Local platform, with GPU capacity sized for your use case. Models run inside your own network, and nothing leaves the building unless you decide it does.
Everything is set up as code and monitored centrally, so your own team can run it. Where public cloud AI does fit, for training or non-critical workloads, we set up Foundry in Azure with the same code and the same central monitoring. That way cloud and local stay one environment.


What is it, exactly
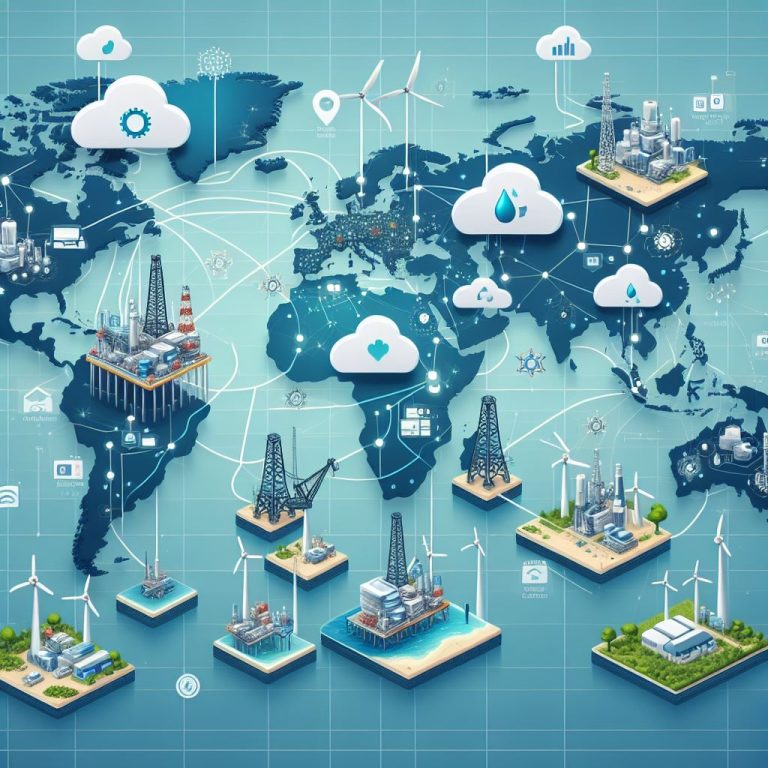
Microsoft Foundry is the service in Azure: a catalog of models, tooling to build agents and applications, and governance over what runs where. Foundry Local is the runtime that runs models on your own hardware, so your data stays on site. Per use case, you choose where a model runs: in Azure or in your own datacenter.

See it run before you invest
Run a real workload with your own data, in our Technology Experience Center or on your own site. Seeing it work beats any presentation.
What's the difference between Microsoft Foundry and Foundry Local?
Microsoft Foundry is Microsoft's platform in Azure for building and running AI applications: a model catalog, tools for agents, and governance. Foundry Local runs AI models outside Azure, on your own hardware. On Azure Local it runs on Kubernetes with Azure Arc management, so the models serve your users from your own datacenter.
Which AI models can run on our own hardware?
Foundry Local runs models from Microsoft's catalog that are prepared for local hardware, including open-weight language models. Which ones fit depends on your GPU capacity and use case. We help you choose a model that matches both.
How do you keep AI experiments under control?
By running them on one platform instead of a collection of separate tools. Foundry gives you guardrails: who can use which models, content filters, and logging of what goes in and out. That turns one-off experiments into something IT can govern and audit.
Other products


Other solutions

Artificial Intelligence
Run AI on GPUs inside your own datacenter, so your data stays where you put it.
Navigation
Important links
Contact details
Socials

